AI search visibility tells you whether answer engines mention your brand or cite your pages for a defined set of questions. It is useful, but it is not a ranking, traffic, lead, or revenue metric. A defensible program starts with a documented sample, records what each engine returned, and reports uncertainty instead of turning a volatile observation into a promise.
DEFINE THE MEASUREMENT BEFORE COLLECTING DATA
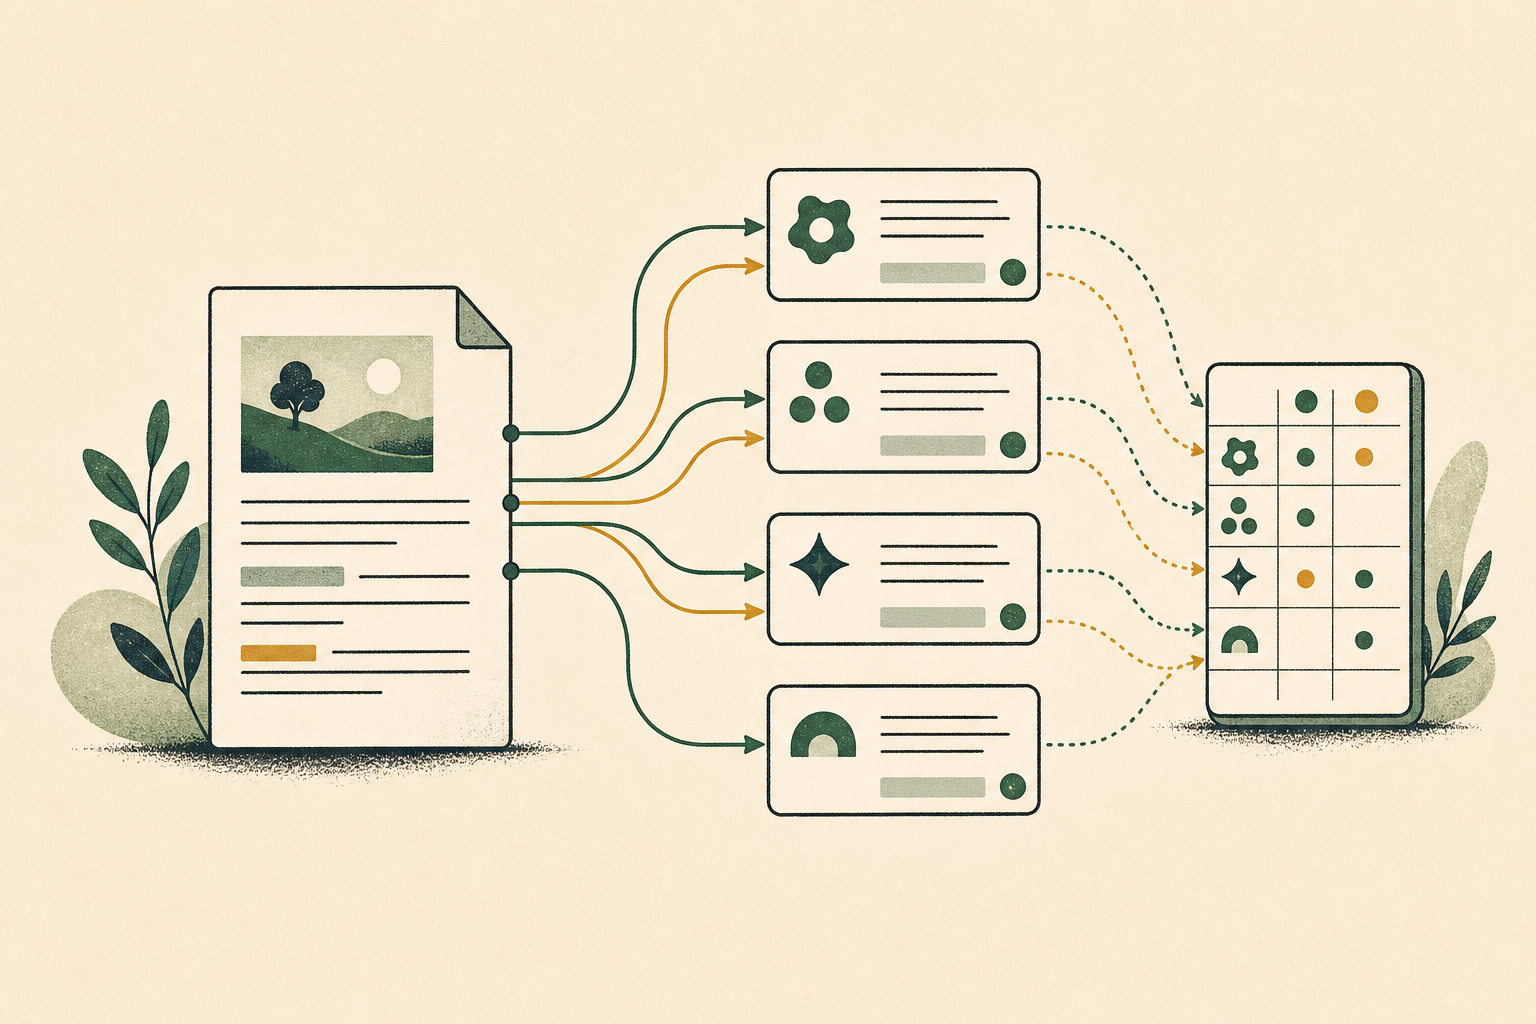
Start with a written measurement scope. Name the audience, topics, markets, answer engines, devices or account states, and reporting period. Decide whether you are measuring any brand mention, an explicit link, a quoted passage, or a cited source. Those events are different and should not be collapsed into one score.
Use separate fields for mention presence, linked citation presence, cited URL, description accuracy, competitor co-mentions, and response date. You may record answer position for context, but do not present it as a standardized relevance score. Model interfaces and source-selection behavior differ, so cross-engine comparisons require care.
BUILD A PROMPT SET YOU CAN REPEAT
Choose prompts that reflect real decisions your audience makes. Include unbranded discovery questions, problem-aware questions, solution comparisons, and a small set of branded questions. Keep the wording stable within a reporting period, and store every prompt in a versioned sheet or database.
There is no universal best number of prompts, repetitions, or weeks. Start with a set your team can run consistently. Repeat prompts when resources allow and retain every result, including misses. A change in prompt wording, model, account state, location, or date can change the answer, so record those conditions with the result.
SEPARATE MENTIONS, CITATIONS, AND OUTCOMES
A mention means the answer names the brand. A citation means the interface attributes information to a page or domain, usually through a link or source callout. A favorable description without a link is still a mention, while a linked source can appear without a strong endorsement. Report both counts and inspect description accuracy separately.
Downstream outcomes belong in another layer. AI referral sessions, branded searches, conversions, and qualified leads can be reviewed beside citation visibility, but correlation does not establish causation. Keep these business metrics separate so stakeholders do not read a visibility change as proof of pipeline or revenue impact.
RUN A REPEATABLE MULTI-ENGINE COLLECTION
Create one record per prompt, engine, and run. Capture the date, prompt version, engine, mention status, citation status, cited URL, answer notes, and any competitor co-mentions. Manual collection is enough for a pilot if the workload is modest and the protocol is consistent. Automation becomes useful when the sample grows or multiple clients need the same reporting cadence.
Keep engine results disaggregated. Google AI Overviews, ChatGPT, Gemini, Claude, and Perplexity do not expose identical experiences or select sources in identical ways. An improvement in one system should not be generalized to all systems. If an interface changes, note the change rather than forcing the new result into an old benchmark.
REPORT TRENDS WITH CLEAR LIMITS
A simple report can show observed mention rate, observed citation rate, cited-page distribution, description-accuracy issues, and competitor co-mentions. Calculate each rate from the documented sample: events divided by completed runs. Always show the prompt count, run count, engines, dates, and exclusions beside the percentage.
Compare periods only when the protocol is comparable. Use a documented peer set and identical prompts for competitor comparisons. Highlight durable directional movement, but also show the range of variation between runs. Avoid invented industry medians and proprietary-looking 0–100 scores unless the method and source are explicitly defined.
TURN FINDINGS INTO CONTENT DECISIONS
The most useful output is not a vanity dashboard; it is a prioritized worklist. Pages cited repeatedly can reveal formats or topics that answer engines currently use. Important prompts with no accurate mention can expose coverage gaps, unclear entity information, or weak supporting evidence. Treat these as hypotheses for editorial review, not guaranteed optimization tactics.
Connect the findings to your existing SEO content audit and topical-authority plan. Improve factual clarity, source quality, internal linking, and page maintenance where the evidence supports it. Then rerun the same sample and document what changed. This makes AI visibility a bounded research signal that informs content operations without replacing search performance, analytics, or customer research.
AI citation tracking is most credible when the method is boringly repeatable. Fix the sample, record the conditions, separate mentions from citations, keep business outcomes in their own layer, and report limitations beside every trend. That discipline gives teams a useful early signal while protecting clients from conclusions the data cannot support.